Non-technical users don't ask fully-specified questions. Nodal makes the gaps visible before SQL runs — so widening access doesn't scale plausible-but-wrong answers. And every interaction is captured: your data team sees who asked what, when, and how it was interpreted — attributed and traceable.
- Question reframed with defaults from your documentation; assumptions in brackets the user can change.
- Confidence score from auditable signals — entity resolution, schema grounding, doc coverage, context freshness.
- You approve the interpretation, not the SQL.
- Every question, every answer, every escalation — logged to your data team's Slack channel with full attribution.
- Every under-specified question becomes a signal — and a candidate test case for the eval suite.
Claude
You
How does length of stay compare across facilities in the Northeast?
Claude
Your question, disambiguated
What is the [mean inpatient days] per facility for [all facility types] in [the Northeast region] over [trailing 12 months — assumed]?
Defaults pulled from your documentation. Change any [bracket] before I run it.
Where each default came from
- "mean inpatient days" — dbt model fct_encounters: discharge_date - admission_date (Confluence confirmed)
- "Northeast" — dim_facilities.region = 'Northeast' (found in 12 dashboards)
- "all facility types" — no filter specified; you may want acute care only
- "trailing 12 months" — assumed; not stated in your question
Confidence score
71/100
- Core metric well-documented across sources
- Join path validated in dbt lineage
- Time window assumed
- Facility scope may be broader than intended
Should I run this, or would you like to change any of the defaults?
You
Narrow to acute care only. Run it.
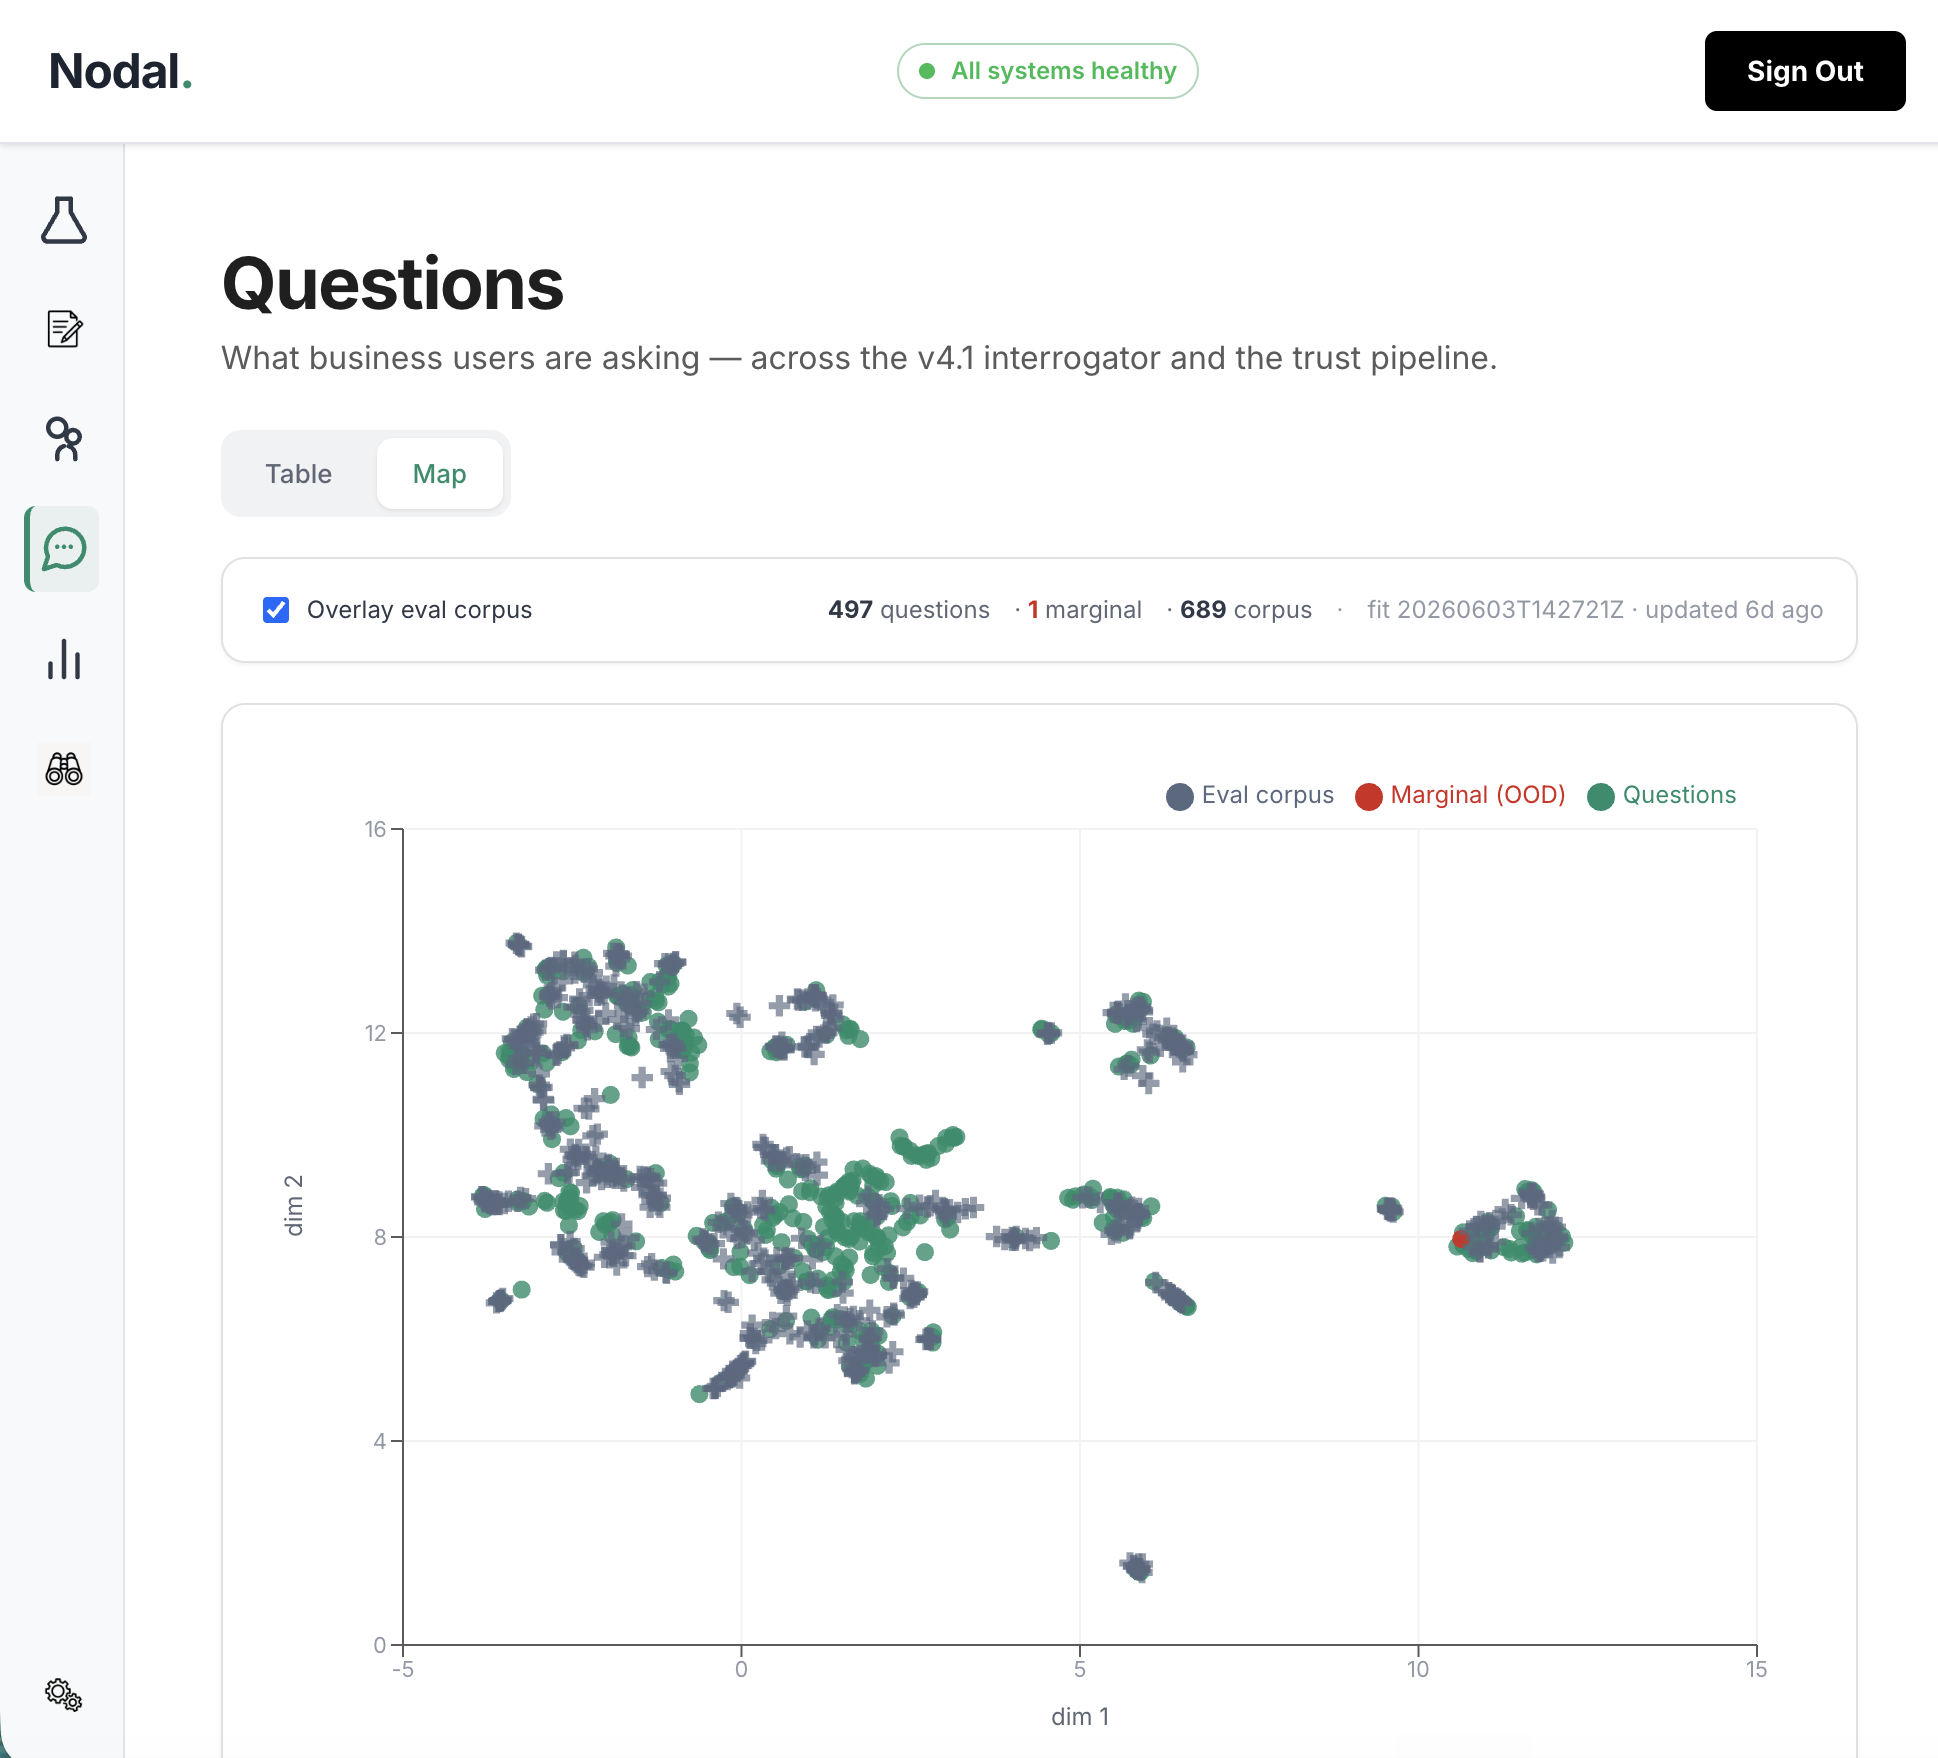
Coverage map — questions asked vs. validated coverage; out-of-distribution flagged for review
Observability — the full loop in action